Tavus Griffin: The First AI Model That Can Hold Real-Time Face-to-Face Conversations
Originally published in Turkish. Read the original →
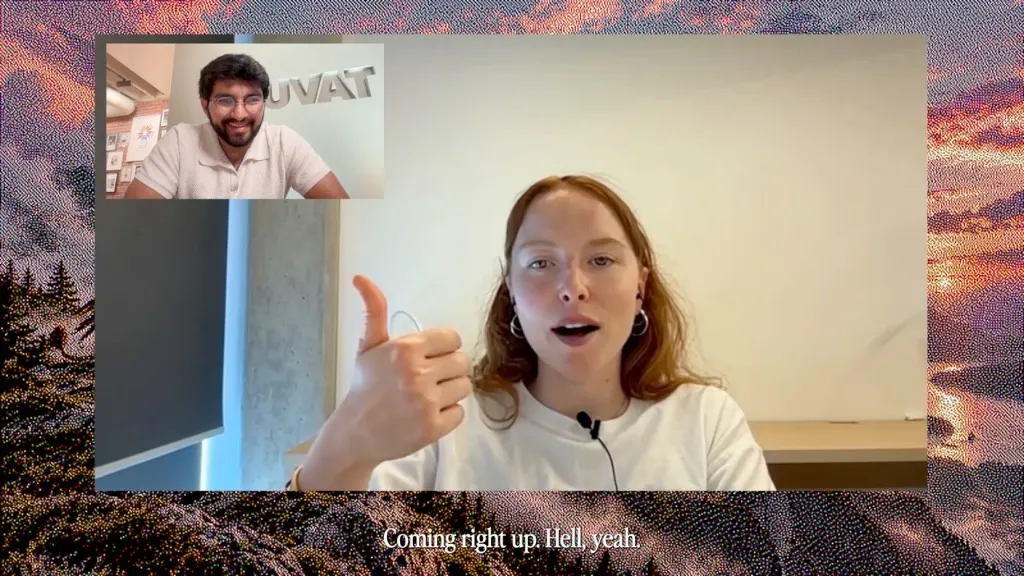
Announced by Tavus, Griffin is a groundbreaking Human Interaction Model (HIM) that understands gestures and facial expressions in real-time video calls and gives human-like instant reactions.
The voice- and text-based chat systems developed in the AI ecosystem so far have relied on the logic of users giving a specific command or finishing their speech completely and then waiting. This classic approach, which determines turn-taking in sequential steps, largely ignored facial expressions, eye contact, pauses and instant reactions, the most basic parts of natural human communication. Tavus, a company that develops generative video and voice technologies, announced Griffin, a new AI model that aims to fundamentally transform these dynamics.
Positioned as a different category from traditional large language models (LLMs), Griffin is considered the pioneer of a new class referred to in the industry as the Human Interaction Model (HIM). During a video call, the model analyzes not only the words being said but also the other person's facial expressions, gaze direction, body movements and pauses simultaneously, and it can produce voice, facial expression and gesture responses with human naturalness.
Beyond Traditional Sequential Models: The Full-Duplex Architecture
Classic AI voice assistants usually work in a three-stage loop: speech is converted to text (STT), the language model generates a response (LLM), and then the generated text is voiced (TTS). This sequential process leads to delays that break the natural rhythm of conversation and to robotic communication. When the user pauses for a few seconds to think, the system may assume the sentence is over and interrupt, or jump in unnecessarily.
Tavus Griffin solves this problem with a Full-Duplex architecture of sub-second mini turns. The model continuously recalculates the state of the conversation on a millisecond basis. This way, while the user has not yet finished speaking, the system can make a small nod to show it is listening, make acknowledgment sounds like "uh-huh" or "I see", or step in at exactly the right moment and take over the turn.
You can watch the impressive live interaction demos the Tavus team performed with Griffin in the official announcement post below:
A Striking Success in a Real-Time Video Turing Test
The success of text-only or voice-only AIs at fooling people has reached very high levels today. But when it comes to live video streams and instant visual reactions, the human eye can easily spot even the slightest artificiality. In an extensive user test conducted by Tavus, Griffin managed to break this perception.
In the blind tests conducted, 54 participants were told they would have a standard one-minute video call with another person. However, on the other side of the screen was a PAL (digital human representation) running on the Griffin-Lite infrastructure, with its voice and video generated in real time. At the end of the call, 48 percent of the participants firmly believed that the person they were talking to was a real human. More than half of the participants had no suspicion at all during the call that the other side might be an AI.
- In detailed satisfaction and naturalness ratings on a 7-point scale, Griffin-Lite achieved the following scores:
- Natural Appearance: 5.4 / 7
- Sense of Trustworthiness: 5.6 / 7
- Desire to Talk Again: 5.8 / 7
- Perception of Truly Being Listened To: 5.5 / 7
Griffin's Dual-Engine Technical Infrastructure
Tavus engineers built the Griffin model on two main components that do not work independently of each other:
1. Continuous Conversational Modeling
This engine listens to and examines incoming audio and video signals simultaneously. It checks the micro-expressions on the other person's face, their gaze direction, an object they hold up to the camera or their speaking tempo dozens of times per second and decides which control signals to generate.2. Audio-Visual Generation Engine
Using the control signals from the conversation model, it creates audio and pixel-level video streams within milliseconds. Griffin is not a simple avatar that only moves the head area; starting from a single reference frame, it fully synthesizes the torso, shoulder movements, hands, fingers, shadows and background lighting in real time.Nvidia VideoFDB Benchmark Results
Griffin-Lite's capabilities were also confirmed by independent tests. On Nvidia's VideoFDB benchmark, which measures bidirectional visual and auditory interaction performance, the model achieved a clear advantage over its rivals:
- Visual and Audio Generation Quality (out of 5): Griffin-Lite scored 3.83, while the human reference was set at 3.92. In the same category, the Gemini 2.5 + Anam combination stayed at 2.80.
- Interaction and Ability to Understand the Other Party (out of 5): Griffin-Lite scored 3.73. In this category the human reference was 4.20, while the MiniCPM-o 4.5 model reached 3.44, Gemini 2.5 Flash Native 3.17 and OpenAI gpt-realtime 2.97.
Potential Use Cases and Safety Measures
Human Interaction Models open up new possibilities across a broad range, from customer relations to education. For example, a digital teacher can tell from the hesitation in a student's facial expression that they are stuck on a problem and change its teaching approach. In customer support, when a user shows a broken device to the camera, they can get instructions directly about the part without needing to know any technical terms.
Such realistic video and voice synthesis capabilities also bring serious security risks such as deepfakes and social engineering fraud. For this reason, Tavus has not yet made the Griffin-Lite model directly available to the public. The company continues to test the model only with authorized research partners until it completes transparency and safety mechanisms that clearly state that it is an AI.




