TÜBİTAK BİLGEM Unveils Bilge, a Domestic AI Model: A New Era in Digital Sovereignty
Originally published in Turkish. Read the original →
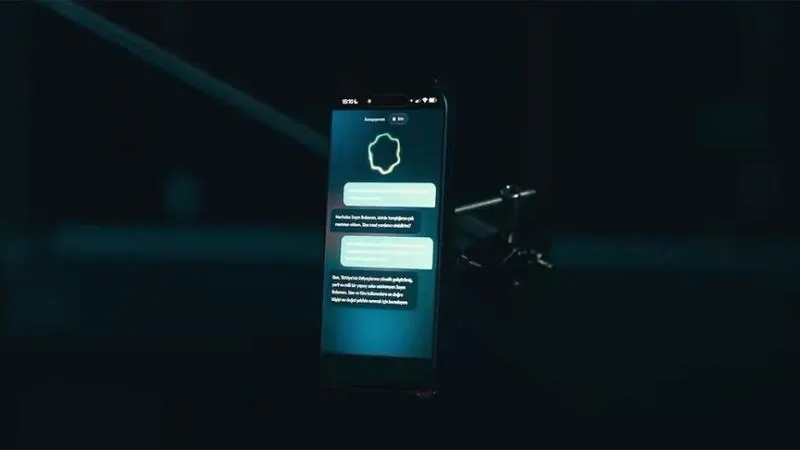
BİLGE, the domestic large language model and one of Turkey's most important steps in AI, has been officially unveiled by TÜBİTAK BİLGEM. We take a close look at the capabilities, development process and security warnings of this domestic AI model, trained on the TRUBA supercomputing infrastructure and focused on the structure of the Turkish language.
Globally, AI technologies have gone beyond being mere software tools and have become the focus of states' strategic priorities, technological independence and struggles for digital sovereignty. While large language models (LLMs) from tech giants such as OpenAI, Google, Anthropic and Meta sweep the world, building domestic infrastructure that protects each country's own cultural fabric, language structure, historical heritage and sensitive data has become an unavoidable necessity.
One of the most concrete and exciting steps in this strategic vision has been taken in Turkey. BİLGE, a domestic and national AI model developed by the Artificial Intelligence Institute (YZE) within TÜBİTAK BİLGEM (the Informatics and Information Security Research Center of TÜBİTAK, Turkey's Scientific and Technological Research Council), has been officially unveiled to the public. Announced by Minister of Industry and Technology Mehmet Fatih Kacır as part of the Türkiye AI Summit, the model demonstrates the country's determination to become a self-sufficient player in the AI ecosystem.
Digital Sovereignty and the Importance of Domestic Large Language Models
Because globally used large language models are generally trained on English-heavy datasets, they often fall short on the grammar rules, cultural codes, idioms and historical contexts of Turkish and similar languages. Moreover, since every query sent to these models means data is processed on servers abroad, they carry serious risks in terms of information security and data sovereignty.
The BİLGE project developed by TÜBİTAK BİLGEM aims to close exactly this gap and let Turkey draw its own AI boundaries. Trained with all the morphological, semantic and cultural features of the Turkish language at its core, this model family offers a secure and optimized alternative across a wide range, from public-sector applications to the private sector. Having a domestic and national LLM infrastructure will allow Turkey to process its own data within its own borders, while critically reducing dependence on foreign technologies.
What Is BİLGE and What Can It Do?
BİLGE is essentially a Turkish-focused large language model family with capabilities in text understanding, text generation, classification, summarization and question answering. Similar to classic AI assistants, it is designed to hold natural conversations with users, answer complex questions and generate content according to given instructions.
The model's key features can be summarized as follows:
* Design Aligned with Turkish Morphology: It has gone through special tokenization (splitting into meaningful pieces) processes to fully fit Turkish's agglutinative structure and complex language rules. * Public-Sector-Focused Integration: One of the model's primary goals is to speed up bureaucratic processes in public institutions, automate services offered to citizens with AI and analyze official correspondence. * Information Security: Thanks to its ability to be hosted entirely on domestic servers, it offers full control over the processing of classified data.
During BİLGE's unveiling, a video of the AI conversing with the Minister of Industry and Technology clearly showed the model's ability to understand natural language and maintain context. However, technical details such as the model's parameter count, layer architecture and the distribution of the specific datasets used in training have not yet been shared publicly in detail. TÜBİTAK will disclose this information over time through its official channels as the model matures.
The Power Behind BİLGE: TRUBA and the ARF-ACC Supercomputer
Training large language models requires not only datasets of billions of words but also enormous computing power and advanced hardware infrastructure. While training BİLGE, the TÜBİTAK BİLGEM team made use of the TRUBA (Turkish National Science e-Infrastructure) supercomputer systems, one of Turkey's most important investments in AI.
Operated by TÜBİTAK ULAKBİM, TRUBA has been strengthened with the recently commissioned ARF-ACC infrastructure, one of Turkey's most powerful supercomputers. Equipped with next-generation graphics processing unit (GPU) technologies such as NVIDIA H100 and H200, this infrastructure makes it possible to train massive models like BİLGE with billions of parameters. Turkey having supercomputing power and a GPU cluster at this level is the strongest guarantee that domestic AI models will not remain mere lab projects but reach levels that can compete by global standards.
Critical Security Warning: Bilge Is Not Yet Available
After BİLGE was officially unveiled, TÜBİTAK issued a very important security warning. Malicious actors, seizing on the excitement in the AI space and the emphasis on a "domestic model", have started offering fake apps, websites and browser extensions online under names such as "BİLGE Yapay Zeka", "TÜBİTAK Bilge Portalı" or "Yerli ChatGPT" (Domestic ChatGPT).
The statement from TÜBİTAK BİLGEM emphasized the following points:
1. Model Access Status: The BİLGE model has not yet been released for general use or a public testing process.
2. Fake Platforms: No app on the internet or in mobile app stores that claims to offer a service under the name "BİLGE" has any connection to TÜBİTAK. Such software can lead to data theft or the spread of malware.
3. Official Communication: All processes related to BİLGE's terms of use, API access or public interface will be announced only through TÜBİTAK's official websites (tubitak.gov.tr or institute pages) and verified social media accounts.
To protect their personal data and avoid cybersecurity risks, users should not sign up on any platform outside official announcements, share their credentials or download third-party files.
Turkey's AI Action Plan and Ecosystem Calls
The announcement of BİLGE is not a standalone technology move but one of the most critical milestones of the "Türkiye AI Action Plan" coordinated by the Presidency. This action plan aims for Turkey to increase academic research in AI, train qualified human resources, securely anonymize public data and open it up to R&D, and integrate domestic industry with AI.
Within the framework of this plan, the TÜBİTAK Artificial Intelligence Institute runs "AI Ecosystem Calls" that bring together universities, technoparks, startups and industrial giants. BİLGE is planned to serve as a "foundation model" for vertical models to be developed in partnership with the public sector and industry. This way, different sectors such as finance, healthcare, the defense industry and education will be able to develop their own customized sub-models using BİLGE's infrastructure.
A Domestic Step Toward the Future
The BİLGE large language model is not just an AI software product in Turkey's digital transformation journey but also a symbolic step toward technological independence. Trained on our own supercomputing infrastructure (TRUBA), by our domestic researchers and shaped by the subtleties of the Turkish language, BİLGE will appear in many areas of our lives in the coming years.
Once the technical details are disclosed and it becomes generally available through official channels, there is no doubt that BİLGE will break new ground in Turkey's software and technology world. What falls to us is to support this domestic ecosystem, follow developments from official sources and be more careful than ever about the security risks that AI brings.




