DeepSeek DSpark and DeepSpec: Up to 85% Faster Inference Without Retraining
Originally published in Turkish. Read the original →
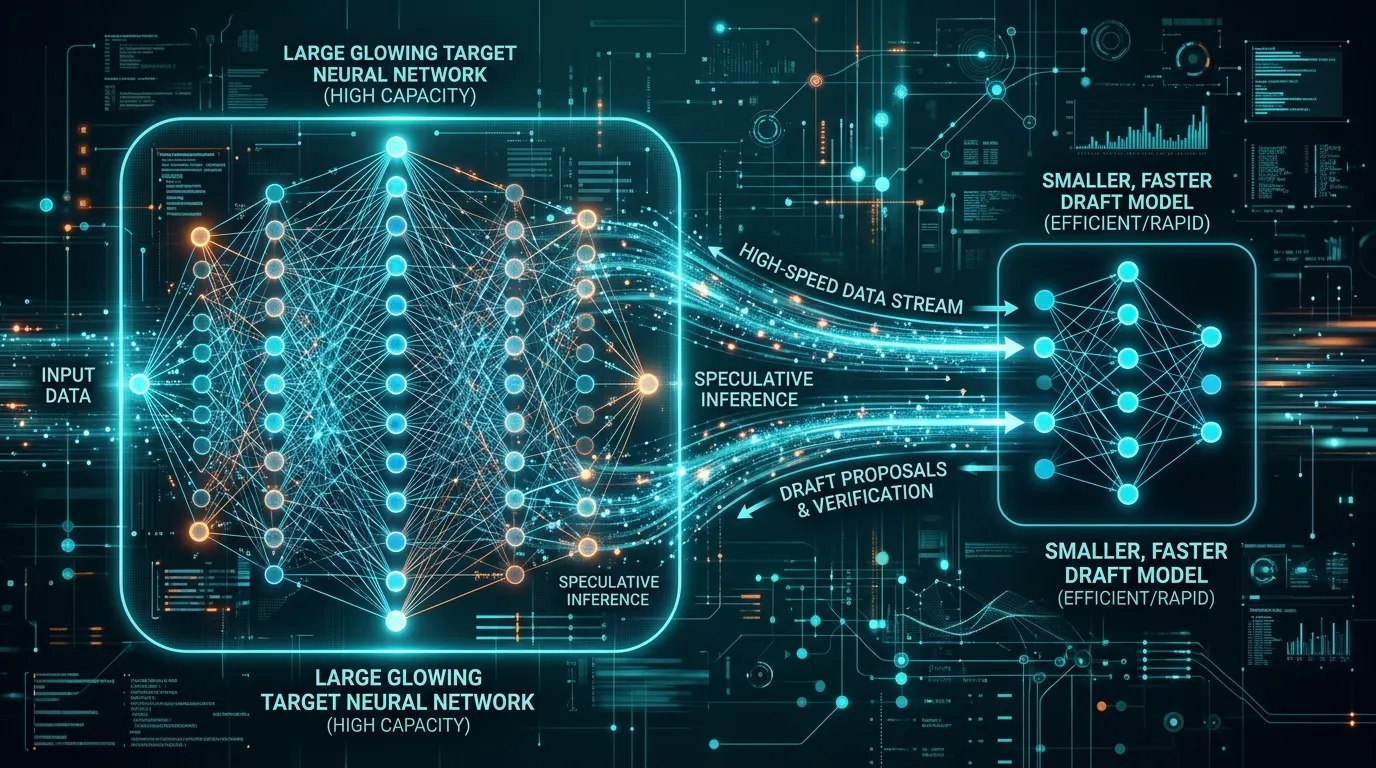
How do DeepSeek's new open-source projects DSpark and DeepSpec speed up inference for V4 models by up to 85% without hurting quality?
Introduction
In live systems where large language models (LLMs) interact with users, one of the most critical performance indicators is text generation speed (tokens per second). No matter how smart a model is, the user experience suffers when the number of words it produces per second is low. AI engineers usually solve this by shrinking models (distillation/quantization), but that lowers the model's intelligence.
DeepSeek AI, which leads in AI architectural efficiency, removed this dead end entirely with two new open-source tools released at the end of June 2026: DSpark and DeepSpec. These projects increase generation speed by up to 85% without compromising the model's intelligence or output quality, using a purely mathematical technique called Speculative Decoding. In this guide, I look at how DSpark and DeepSpec work.
---
What Is Speculative Decoding?
Large models (for example the 671-billion-parameter DeepSeek V4) have to run a giant neural network from start to finish for every single word they generate. That is quite slow. Speculative decoding uses two different models to speed up the process:
1. Draft Model: A very small, extremely fast helper model (for example with 7 billion parameters). It quickly "guesses" (speculates on) the next 5-10 words. 2. Target Model: The large model that is actually smart. It checks the words quickly produced by the draft model in a single processing step (parallel verification). 3. Approval Process: If the large model approves the words the draft model guessed, they are added to the output immediately. If any words are rejected, the large model writes the correct one and the process continues.
This way, instead of running once for each word, the large model approves in one go the blocks the small model guessed correctly, which yields a very significant speedup.
---
What Sets DeepSeek DSpark and DeepSpec Apart
This new pair, released by DeepSeek to the open-source community, turns speculative decoding into a standard any developer can easily apply:
DSpark
DSpark is a speculative decoding engine optimized for DeepSeek's own V4 models. It increases text generation speed by 60% to 85% on average while keeping the model's output "byte-identical" (that is, letter for letter the same as what the main model would produce if it ran alone). There is not the slightest loss in the model's reasoning capacity or coding ability.DeepSpec
DeepSpec is an open-source toolkit that lets developers build speculative decoding systems for their own custom models or datasets. With DeepSpec you can: * Train and build the best-matched "draft models" for your large models. * Analyze and optimize the acceptance rate of draft models. * Test speculative decoding performance on your own server infrastructure.+--------------------------------------------------------------+
| DEEPSEEK SPECULATIVE DECODING SYSTEM |
+--------------------------------------------------------------+
<div class="overflow-x-auto my-6">
<table class="min-w-full bg-white dark:bg-neutral-900 border border-gray-200 dark:border-neutral-700 rounded-lg shadow-xs">
<thead>
<tr><th class="px-4 py-3 text-xs font-medium text-gray-500 uppercase tracking-wider bg-gray-50 dark:bg-neutral-800 dark:text-neutral-400 border border-gray-200 dark:border-neutral-700">[Small Draft Model] --> Quickly guesses 5-8 words</th></tr>
</thead>
<tbody class="divide-y divide-gray-200 dark:divide-neutral-700">
<tr class="hover:bg-gray-50 dark:hover:bg-neutral-800"><td class="px-4 py-3 text-sm text-gray-900 dark:text-neutral-100 border border-gray-200 dark:border-neutral-700">[Large Target Model] --> Approves / rejects guesses in one pass</td></tr><tr class="hover:bg-gray-50 dark:hover:bg-neutral-800"></tr><tr class="hover:bg-gray-50 dark:hover:bg-neutral-800"><td class="px-4 py-3 text-sm text-gray-900 dark:text-neutral-100 border border-gray-200 dark:border-neutral-700">[DSpark / DeepSpec] --> Delivers 85% speedup without hurting quality</td></tr>
</tbody>
</table>
</div>+--------------------------------------------------------------+---
Benefits for Developers and Teams
Integrating DSpark and DeepSpec into enterprise systems offers these concrete advantages:
* Lower Server Costs: Because servers spend less time processing, the same hardware can serve many more users concurrently. * A Smoother Coding Experience: In IDE integrations, the time it takes for code suggestions to appear drops to milliseconds, providing an uninterrupted typing experience. * Open-Source Flexibility: With these tools distributed under the MIT license, companies can build high-performance AI systems on their own internal servers without sending their data outside.
Conclusion
With DSpark and DeepSpec, DeepSeek has proven once again that efficiency in AI does not end with training models; inference technologies need optimizing too. This 85% speedup, achieved through purely mathematical approaches without bearing the cost of retraining, will further strengthen the open-source AI ecosystem's hand against closed commercial models.




